TinySearchLive

Spend tokens on answers, not webpages.

TinySearch is the smallest web toolkit that lets an agent reliably investigate the open web. It searches, reads, and — when a page refuses to give up its content — drives a real browser, returning only the source-grounded evidence worth putting in the context window.

tinysearch / research

A search result is not yet evidence.

Agents open several pages, ingest navigation, footers and cookie banners, and spend paid input tokens deciding which paragraph mattered. TinySearch moves that work in front of the model: search broadly, read locally, and pay only for the passages that survive.

Both columns below are the same eight research queries over the same crawled pages. The only difference is what reached the model.

evidence.diff

- Search, then fetch

  • Whole pages, boilerplate included
  • Relevance decided in-context
  • 18,360 tokens per query

+ TinySearch

  • Ranked passages only
  • Relevance decided before the model
  • 6,678 tokens per query

Four primitives, composed by the model.

TinySearch does not one-shot your question. Every step is independently callable, so the agent can inspect evidence, change direction and follow up. Nothing is hidden behind a monolithic research call it cannot steer.

  1. get_current_datetimeground the question in real time
  2. searchdiscover candidate sources
  3. scrape_urlsread the pages worth reading
  4. browser_*interact when reading is not enough

One command, or the full stack.

Start with a single uvx MCP command and no search service, or deploy the Docker and SearXNG stack for a shared network endpoint.

Fast search starts without Chromium or an embedding model. The first scrape initializes Chromium; focused scraping also loads the embedding model. Run tinysearch setup to pre-warm both.

Five MCP tools and a Python API.

The tool surface stays small on purpose. MCP re-sends every schema to the model on every request, so a wide toolbox is a permanent tax on the very context window it is supposed to protect. The MCP tools return grounded prompts; the Python API and FastAPI app return structured JSON for applications that want to store, inspect or transform the evidence first.

The page that will not be scraped.

scrape_urls is a static fetch. It cannot see content that JavaScript renders after load, content behind a cookie interstitial, a “load more” control, or a client-side search UI. For those pages TinySearch drives a real browser — the same Chromium it already installed for scraping. No second runtime, no second browser, no child process.

The model reads an accessibility tree, names a ref it actually saw, and TinySearch acts on it with genuine browser input events. Nothing invents CSS selectors. No tool can execute code: there is no evaluate, no form filler, no upload. A page that injects instructions into its own rendered text has nothing dangerous to reach for, because the capability is absent rather than discouraged.

browser session
browser_navigate
  url:  "https://example.gov/registry"
  find: "Accept"

  - button "Accept all" [ref=e79]

browser_act
  action: "click"
  target: "e79"
  find:   "Results"

  - table "Results" [ref=e112]
    - row "Filing 2026-0417" [ref=e113]

Retrieval, not summarization.

TinySearch selects the passages worth keeping with local BM25 and embedding rerank. It does not run a model over the page to rewrite or condense it, so what you cite is what the page actually said.

That keeps the pipeline fast and free to run locally, at the cost of not compacting as aggressively as a dedicated reduction model could. A learned reduction step is a direction we may explore later; it is not part of TinySearch today.

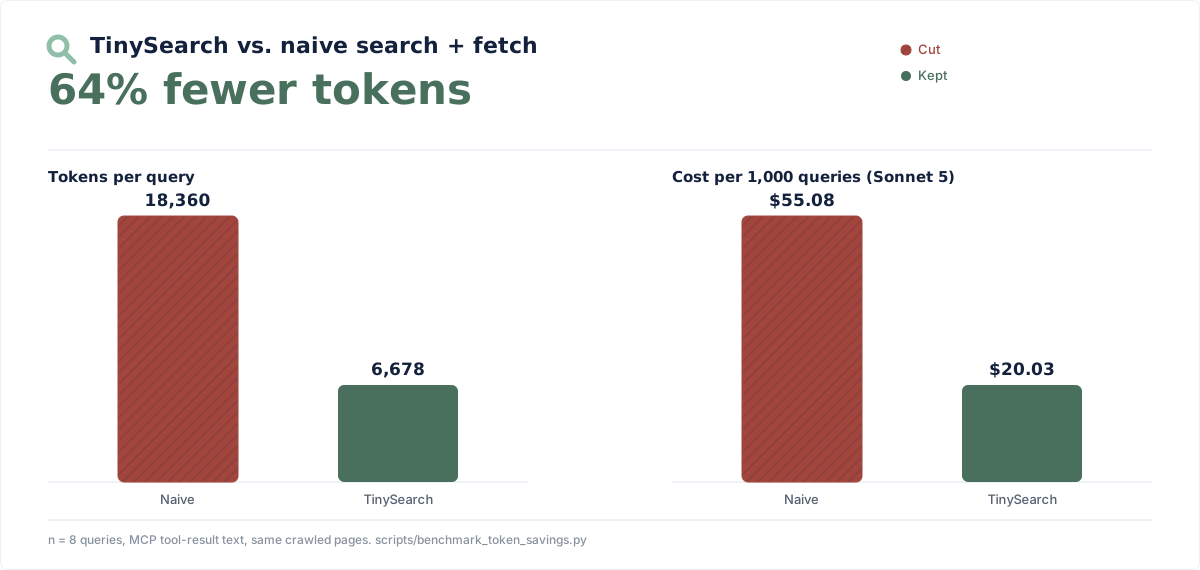
64% fewer tokens, measured on the real tool output.

The baseline is not a strawman: it is the same pages TinySearch crawled, fed to the model unfiltered, the way the web-search-plus-fetch tool built into most coding agents would.

Benchmark chart: TinySearch uses 64% fewer tokens than a naive search-and-fetch agent across eight research queries, 6,678 tokens per query versus 18,360, cutting modeled input cost per 1,000 queries from $55.08 to $20.03.
Eight research queries, counted on the actual MCP tool-result text of the recommended search then scrape_urls flow. The cost panel uses an illustrative $3.00 per million input tokens and excludes search, crawling, model output and downstream agent use. Reproducible from the repository.

You choose the sources, the browser and the exit.

Open-source intelligence work lives or dies on provenance and control. TinySearch keeps both on your side of the wire: no vendor account, no required API key, no hosted cache of what you looked at. Every returned chunk is the original page text, unedited, still attached to its URL — so a claim in your agent’s answer traces back to one specific passage rather than stopping at “the vendor’s model said so.”

A CDP endpoint is privileged remote control of a browser. Keep it on loopback or a private network, and require authentication when it crosses a host boundary. TinySearch never stores credentials, never automates a login, and never accepts a raw selector from a model.

See what your agent actually did.

TinySearch emits vendor-neutral OpenTelemetry traces and metrics today: operation and stage timing, outcomes, result counts, backend state, browser escalations, token counts and embedding model metadata. Point it at any OTLP collector with the standard environment variables.

Telemetry is opt-in and exports nothing until configured. It never exports queries, URLs, domains, prompts, documents, snippets, headers, credentials, raw errors, exception stacks, MCP arguments or MCP results — the operational shape of a run, never its content.

Give your agent evidence, not webpages.

TinySearch is open source and runs on infrastructure you control.